There is a number being put in front of you at every trade show this year. Millions of components analyzed. Thousands of plants. Decades of fault history. The implication is always the same: our artificial intelligence knows more than the others, because it was fed more.
It is an impressive number. It is also the wrong one to compare — and not for a marketing reason. It is how these systems actually work.
Short answer. The general knowledge of vibration analysis — fault frequencies, standards, failure patterns, the four stages of a bearing defect — is published, and every capable language model already carries it. No vendor owns that knowledge and none can sell it to you. What decides whether a diagnosis is right is how much the system knows about your machine — its datasheet, its bearings, its real running speed, its operating modes, its trend, its spectrum, its waveform, the analyst’s notes — and that it has all of it in front of it at once, which is the one thing no person can do: we read one screen at a time. And then whether it is allowed to go and check the things it is unsure about. Ask any vendor to show you both. The size of a training corpus is the easiest claim for them to make and the hardest for you to verify.
Why a bigger training set does not make a better diagnosis
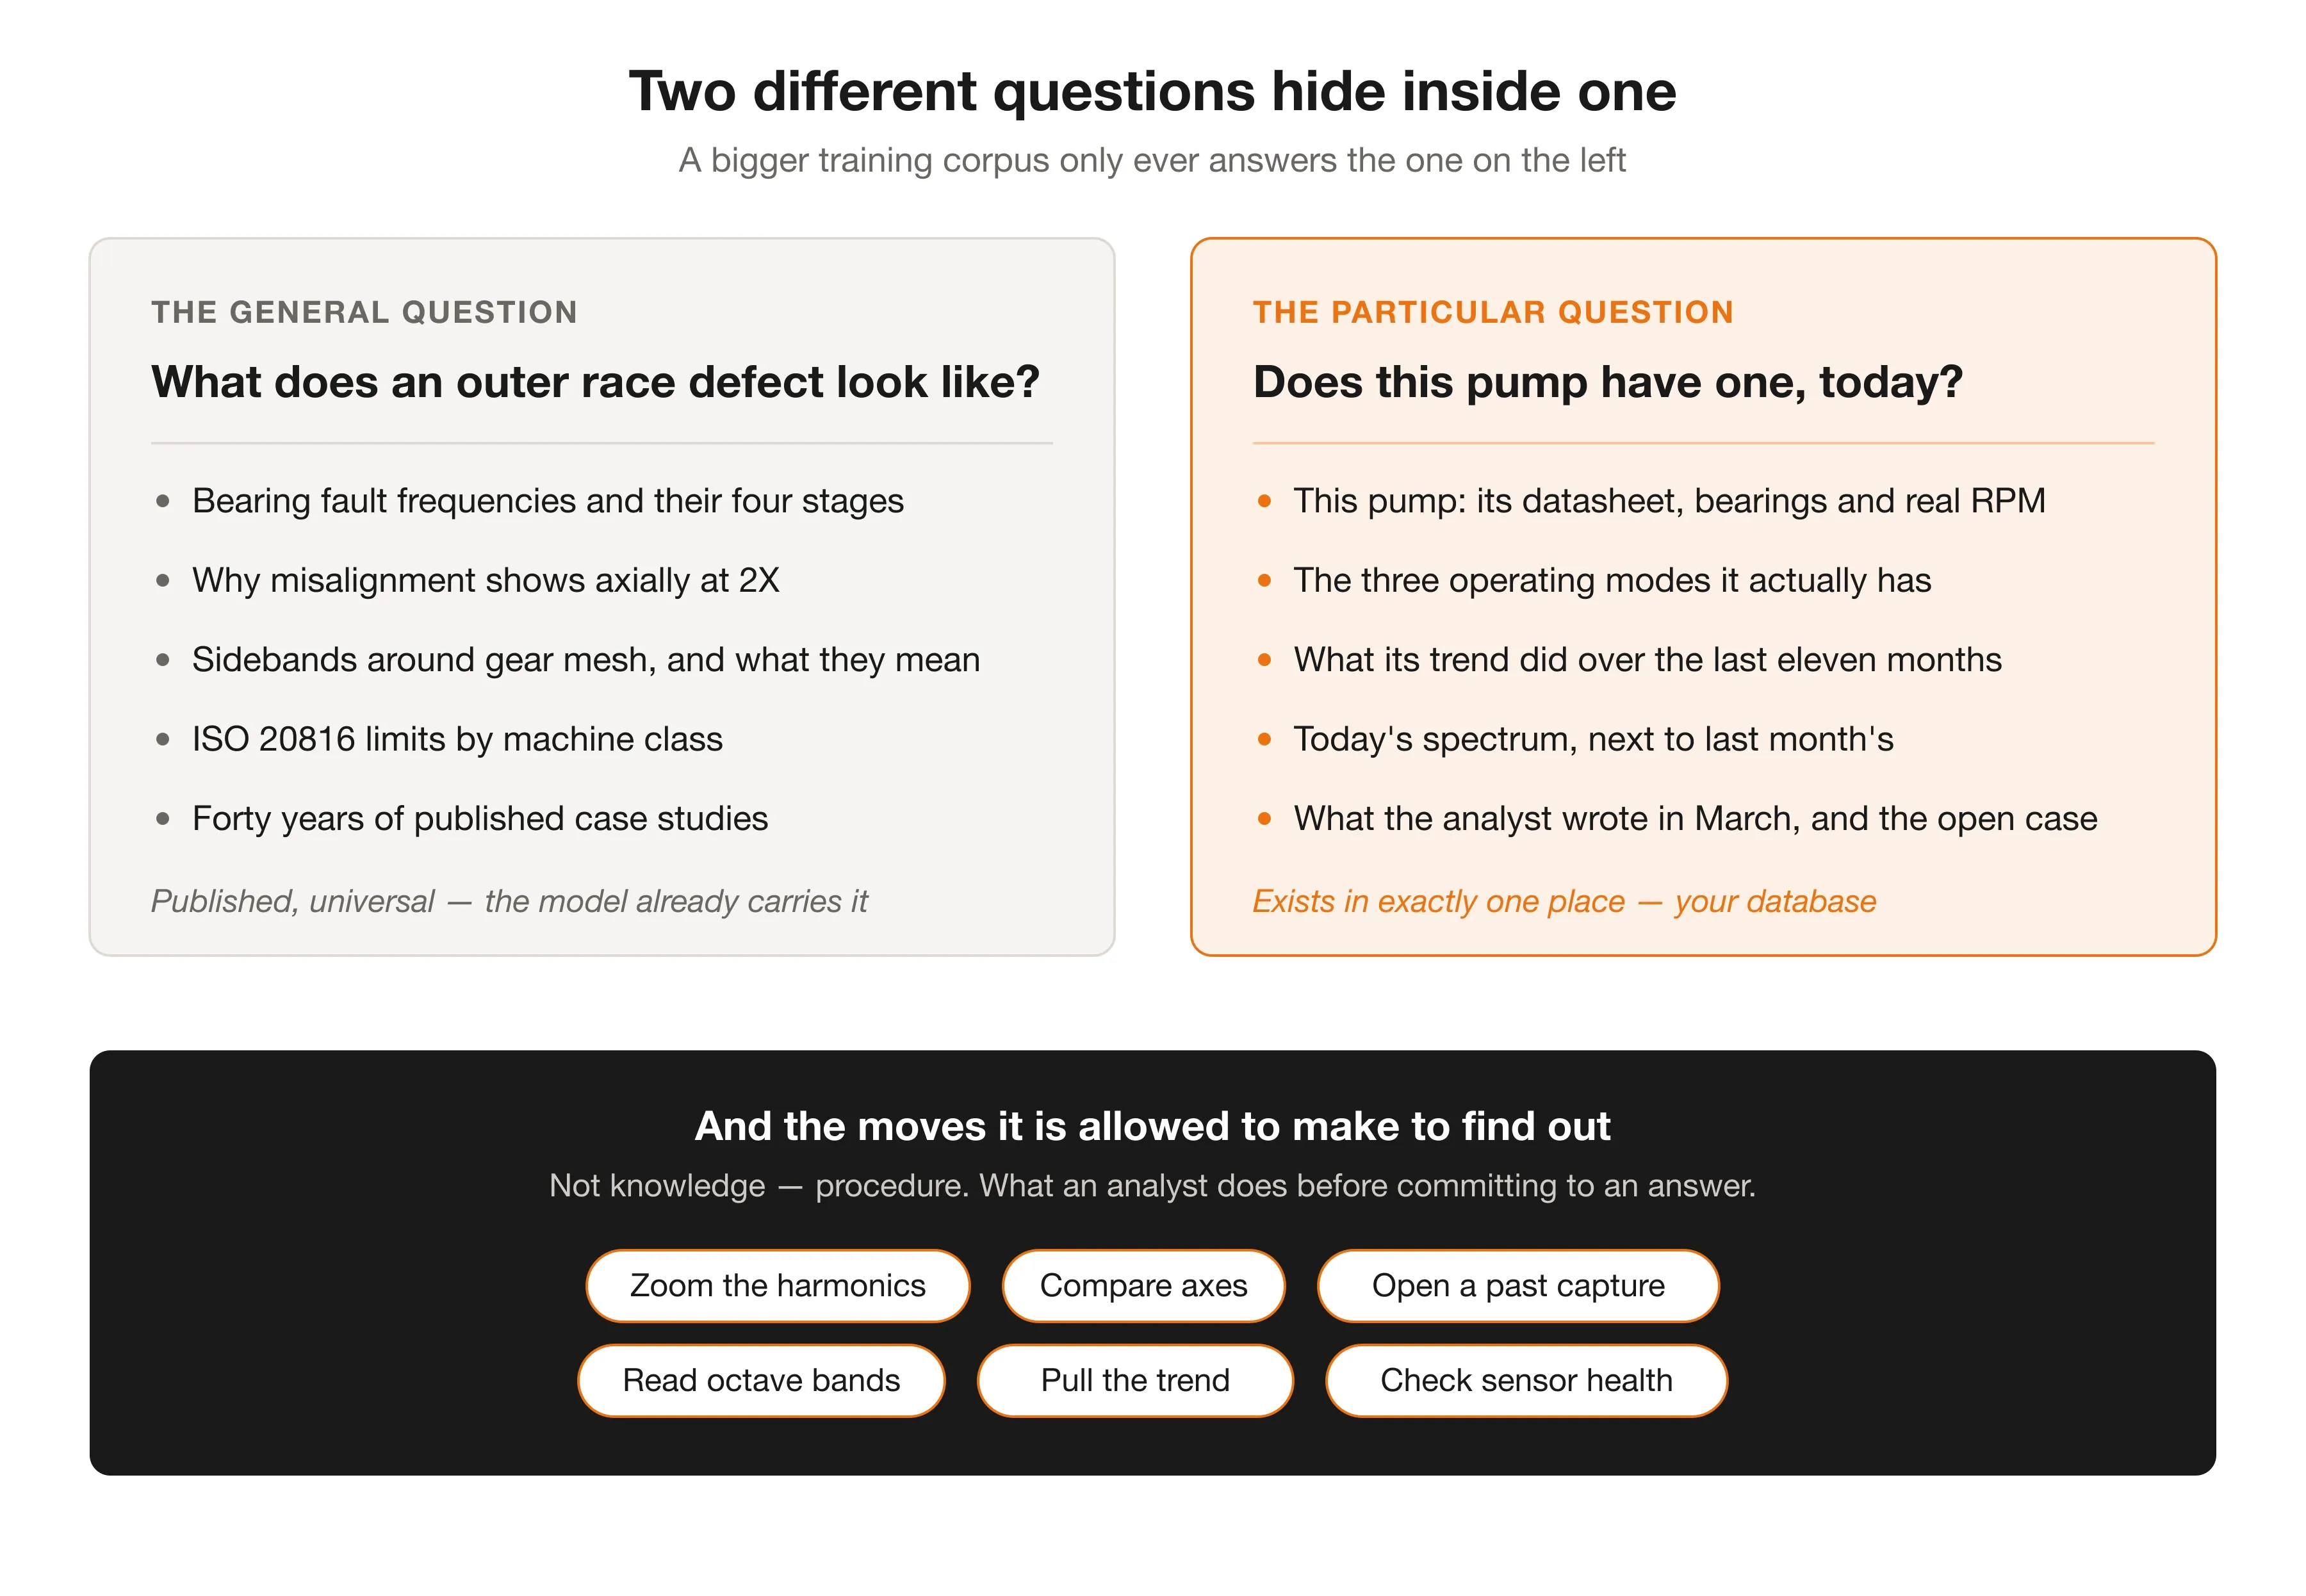
Think about what that number is really selling you: general vibration knowledge. What a bearing defect looks like in an envelope spectrum. Why misalignment shows up axially at 2X. How sidebands around gear mesh reveal an eccentric gear. What ISO 20816 says about a 200 kW machine on a rigid foundation.
None of that is scarce any more. It lives in the textbooks, the standards, the conference papers and forty years of published case studies, and every serious language model has already read all of it. You do not have to buy it from anyone.
What is scarce is something no database of other people’s failures can contain: your machine.
Context is ninety percent of the answer
Which is why the tools matter as much as they do. They are not a second ingredient standing next to context — they are how the system goes and gets more of it when what it was handed is not enough.
A human analyst does not diagnose by staring at one screen. They zoom into the region around 1X to see whether there really are sidebands there. They switch the same measurement to envelope. They pull up the waveform to check whether the impacts are periodic. They compare the horizontal axis against the vertical one. They open the capture from three months ago and put it next to today’s. They check whether the sensor itself is healthy before believing anything it says.
None of that is knowledge. It is procedure — and an assistant that cannot do it is reduced to commenting on whatever screenshot it was handed.
In EI-Analytic™ the assistant is called Erby, and it has those same moves available as tools. It can:
- request the trend for any period
- read the octave bands
- open a specific capture
- zoom into a frequency range
- compare axes, and compare moments in time
- pull the asset datasheet
- check sensor health
- read the plant overview
When it is not sure, it goes and looks, exactly as a person would — and every step it takes is visible to you inside the answer.
The screens below are one real turn on one real pump. Nothing is staged: Erby was asked for a diagnosis, and this is what it did before giving one.
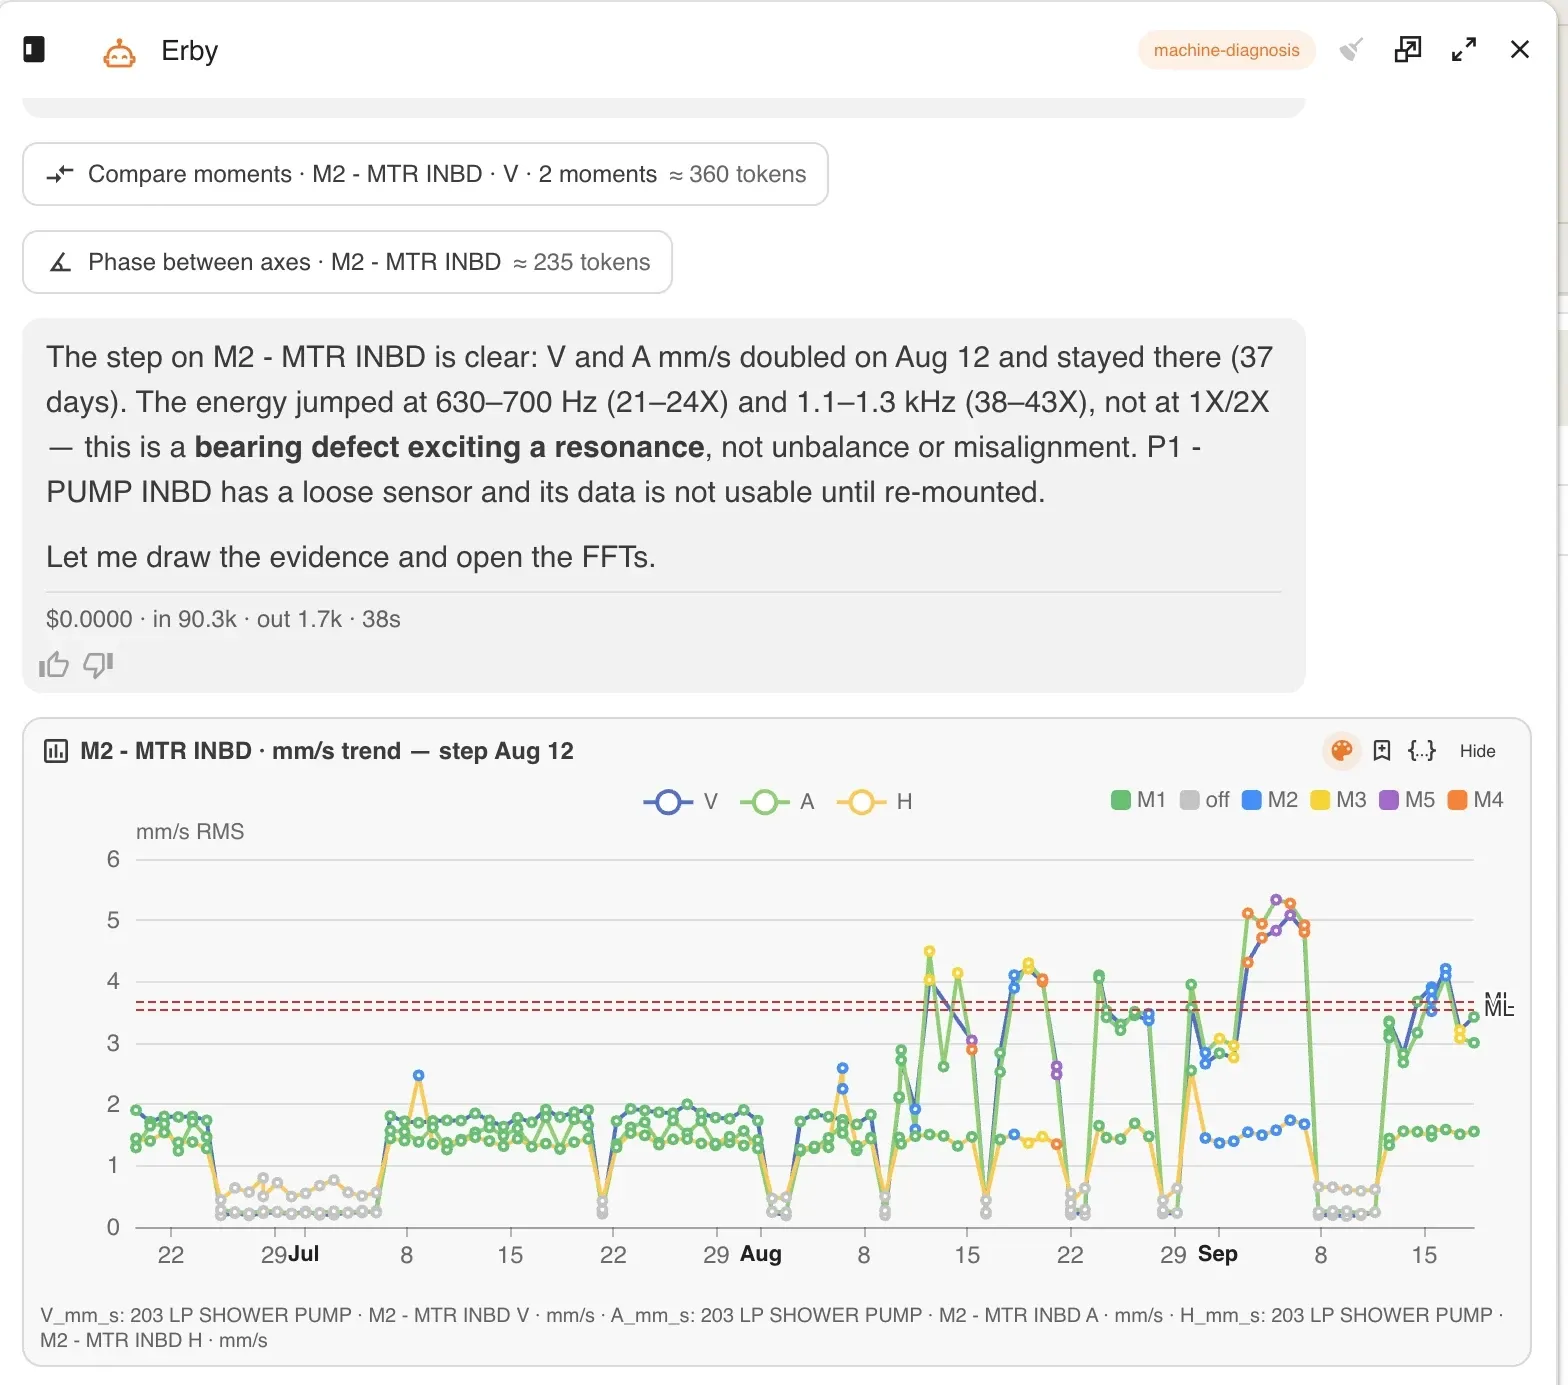
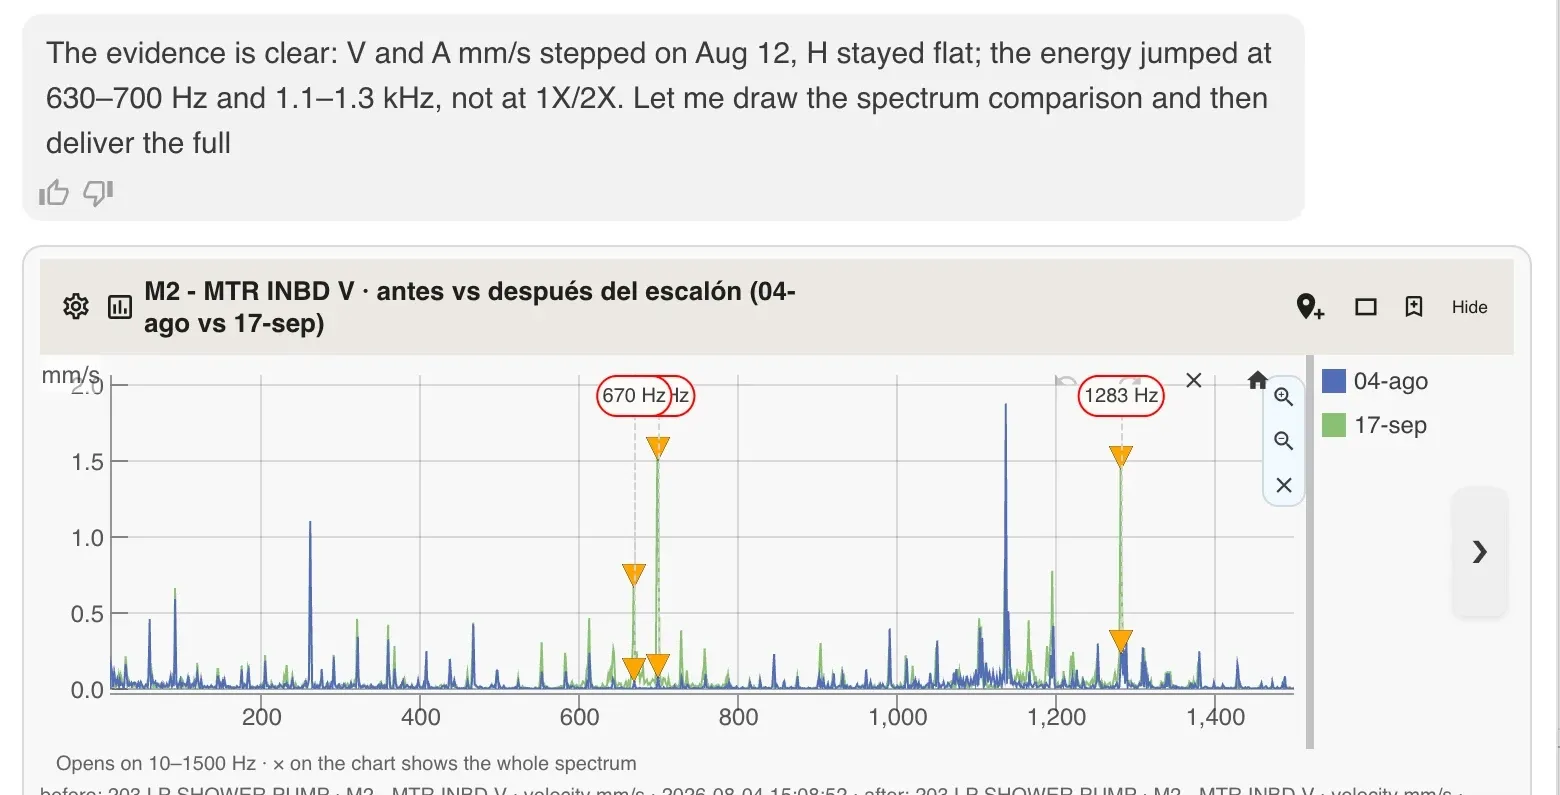
Notice what the conclusion is made of. Not high vibration on the motor, but this: the energy rose at 630 to 700 Hz and at 1.1 to 1.3 kHz, and not at 1X or 2X. Which means a bearing defect exciting a resonance — not unbalance, and not misalignment.
You can prove that sentence wrong. Go to the spectrum and check the numbers. Which is exactly what it does next, without being asked.
So the comparison that matters is not whose training set is bigger. It is how much of the real situation the system can reach, and how many of an analyst’s moves it can actually make.
How EI-Analytic™ builds the answer instead: three layers
It is worth being explicit about which layer does what — because in our software the artificial intelligence is not the one issuing the diagnosis.
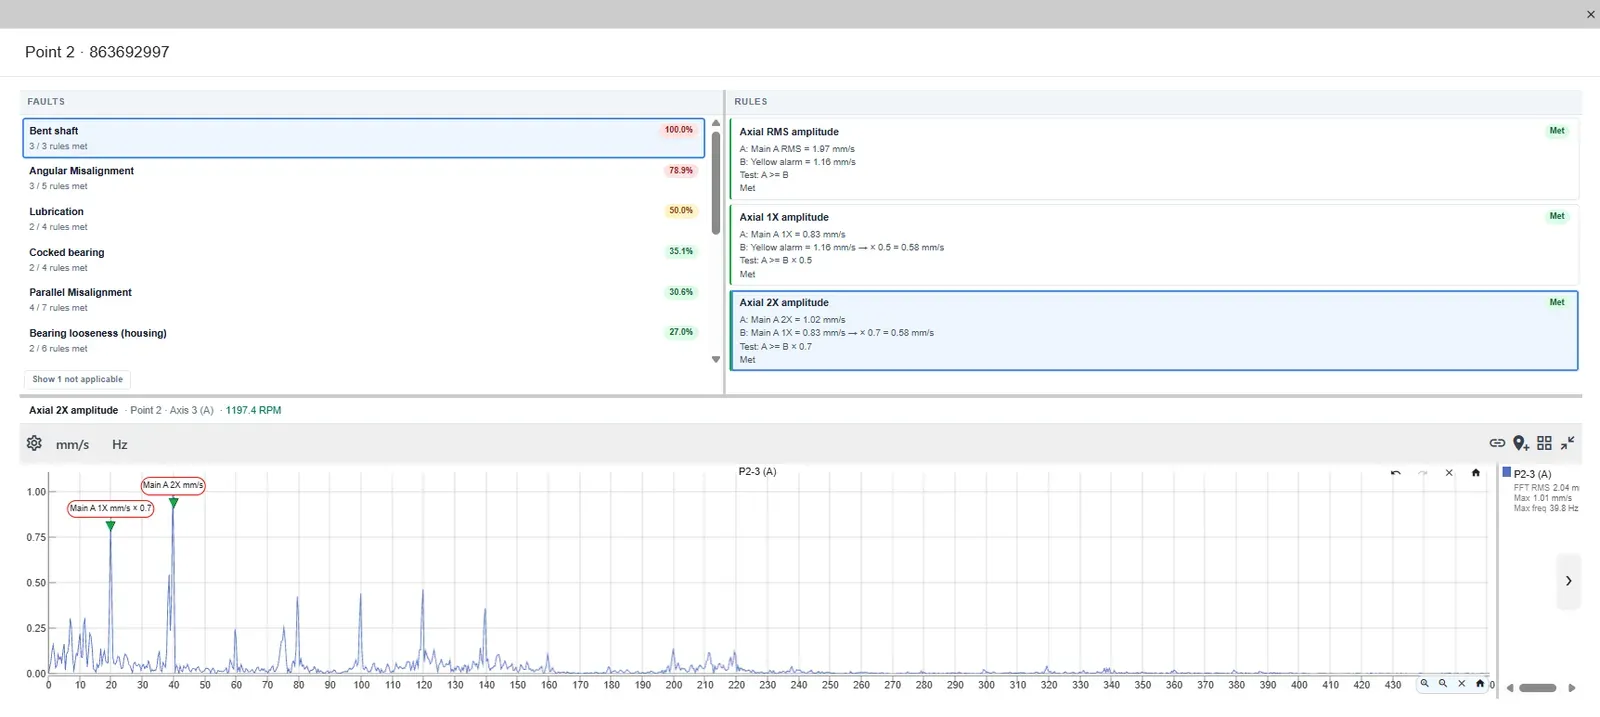
The rule engine names the fault. Thirteen fault types, each one a set of conditions with its arithmetic visible: which amplitude, compared against which, with which factor, met or not met. It works from the very first measurement, with no history and no training. And you can edit every rule when it gets your twenty-year-old fan wrong. This is what produces the diagnosis you see on the dashboard.
Machine learning learns your machine — not somebody else’s. Clustering groups each point’s measurements into the operating modes that machine actually has, with nobody labeling anything, and reports when a mode appears that has never been seen before. Alarm limits are learned from a healthy period you select, on that specific point. Both are trained on your data, about your equipment — the only training that transfers to your decisions.
Erby reads the whole picture and explains it. Before it answers, the software assembles a context package and shows it to you first: which layers go in, how large each one is, and an option to anonymize company and area names before anything is sent. Then it works with the tools above and returns a report with its evidence attached — amplitudes per axis, frequencies, ratios against 1X, bearing fault frequencies from the envelope — so every statement traces back to a measured number.
And the last rule is the one we would not trade for any amount of accuracy: the assistant does not act on its own. It can prepare a case, a note, a route or a report, but the window opens filled in and a person presses save. Your data stays in your platform. Every answer shows what it cost.
The memory that matters is not the model’s. It is yours.
A language model arrives with a generic memory: everyone and everything, averaged. That is a fine place to start and a poor place to finish. So we hand a good part of that memory back, and replace it with something worth far more — the memory the system builds from the analyst who uses it.
How you like your alarms set. Which machines you already decided to ignore, and the reason you gave. That the compressor in area 4 always looks alarming at startup and never is. The way you word a case before you hand it to production. The point at which you stop watching and pick up the phone.
Erby keeps all of that, visibly and undoably, and brings it to the next question. It is not learning vibration from you. It already knows vibration. It is learning you.
The question that actually separates one vibration AI from another
The industry is about to spend a year arguing about whose corpus is larger. It is a comfortable argument for vendors, because it can be asserted and not checked.
The useful question is simpler, and much harder to fake. A vibration AI is only as good as what it knows about the machine in front of it, and what it is allowed to do to find out more. General expertise now comes free with the model. Your machine’s history, its modes, its baseline and its open cases do not — and they are the entire difference between an answer about pumps and an answer about this pump.
We built ours on that assumption. You should make every vendor, including us, show you exactly what their AI is looking at.
FAQs about AI in vibration analysis
Does a bigger AI training dataset make a vibration diagnosis more accurate?
Not beyond a point. The general knowledge a large corpus is meant to buy — fault frequencies, standards, failure patterns, ISO limits — is already published, and every capable language model has read it. Extra examples of other plants’ failures do not tell the system anything about the speed, mounting, operating modes or history of the machine you are actually looking at. That information exists only in your own database.
What does an AI need to know to diagnose a specific machine?
Its datasheet and bearing part numbers, its real running speed, the operating modes it actually has, its trend over time, the spectrum and waveform of the measurement in question, how one axis compares with another, and what the analysts have written about it before. In EI-Analytic™ that context package is assembled from your own database and shown to you before anything is sent, with the option to anonymize company and area names first.
Can an AI assistant check something it is unsure about?
It can, if it has been given tools to do it with. An assistant that only sees a single screenshot can do nothing but comment on that screenshot. Erby can request a trend for any period, open a specific capture, zoom into a frequency range, switch to envelope, compare axes and compare two moments in time — the same moves a human analyst makes, with each step visible in the answer.
Is a failure database useless for condition monitoring, then?
No. It is genuinely useful for a specific set of jobs: sensible starting alarm limits by component type, criticality frameworks, the failure modes worth considering for a class of asset, and how long a given defect usually takes to progress. On a brand-new machine with no history of its own, statistics from similar machines are the best first guess available. What a population cannot do is tell you what one individual machine is doing today.
Can the history of one machine predict what an identical machine will do?
Not reliably. Two identical pumps — same model, same year, same duty — mounted forty meters apart will show different baselines, because foundation stiffness, piping strain and local resonances are not the same. Population data tells you what to expect from that class of machine; only that machine’s own baseline tells you whether something has changed.
Further reading